The Network Engineer's Guide to Latency
Light in fiber moves at 200,000 km/s and the market doesn't care. Latency broken into its four honest components — and how trading and voice engineers actually shave them.
The shout-and-echo analogy
Stand at the edge of a canyon and shout. Your voice needs time to reach the far wall, and the echo needs time to come back. That round-trip gap is latency, and the canyon is just a very slow network. Walk closer to the wall and the echo returns sooner — that is propagation delay: distance divided by speed. Now compare barking the word "go!" with reciting a whole paragraph: the paragraph takes longer to leave your mouth even though your voice travels at the same speed — that is serialization delay: message size divided by how fast you can push bits out.
| Unit | Length | Feels like |
|---|---|---|
| ms — millisecond | 1/1,000 of a second | a camera flash; a blink is ~100–150 ms |
| µs — microsecond | 1/1,000,000 of a second | 1,000× shorter than a millisecond |
| ns — nanosecond | 1/1,000,000,000 of a second | light travels about 30 cm (one foot) in 1 ns |
This article lives in microseconds. When you see "25 µs", read it as "25 millionths of a second — about 4,000× shorter than a blink."
Why latency became a career
In 2010, a new fiber route between Chicago and New York cut the trading round-trip from roughly 16 ms to 13 ms — and that single millisecond-plus advantage was immediately worth more than the cost of laying the fiber. HFT firms pay millions to shave microseconds because the fastest reaction wins the trade.
Low latency is not just a trading curiosity, though. Voice calls start feeling wrong past ~150 ms, gaming and remote surgery live and die on it, and every TCP throughput formula on earth has RTT (round-trip time) in the denominator.
The 30-meter advantage
The exchange's matching engine sits in a data center in Carteret, New Jersey. Trading firms rent rack space — colocation — inside that same building, so their fiber run is 30 meters instead of 1,200 kilometers. The diagram below is the entire HFT latency business in one picture:
The four components
Every delay you will ever chase decomposes into exactly four pieces — memorize them like a recipe:
- Propagation delay — the speed-of-light floor. Distance times ~5 µs/km one-way in fiber. Only shorter paths fix this.
- Serialization delay — how long it takes to push bits onto the wire: packet size ÷ link rate. A 1,500-byte frame takes 12 µs on 1 Gbps and only 120 ns on 100 Gbps. (Think of it as the time to squeeze toothpaste out: a bigger tube or a narrower opening takes longer.)
- Processing delay — the per-device cost: store-and-forward switching reads a whole frame, cut-through starts forwarding after the header (~1–2 µs per hop), routers add lookup time, firewalls add much more.
- Queuing delay — the variable one. When a packet arrives at a busy interface, it waits in the buffer — like joining a checkout line. Empty queue: ~0. Full 10 ms buffer: 10 ms. Queuing is the reason latency dances while bandwidth sits still.
One tick's journey, stage by stage
A market tick is born at the exchange, and the race is to react to it before anyone else. Here is where the microseconds go on a typical colocated path — watch each stage light up in order (illustrative numbers):
Model your own chain in the tick-to-trade calculator.
Why distance beats bandwidth
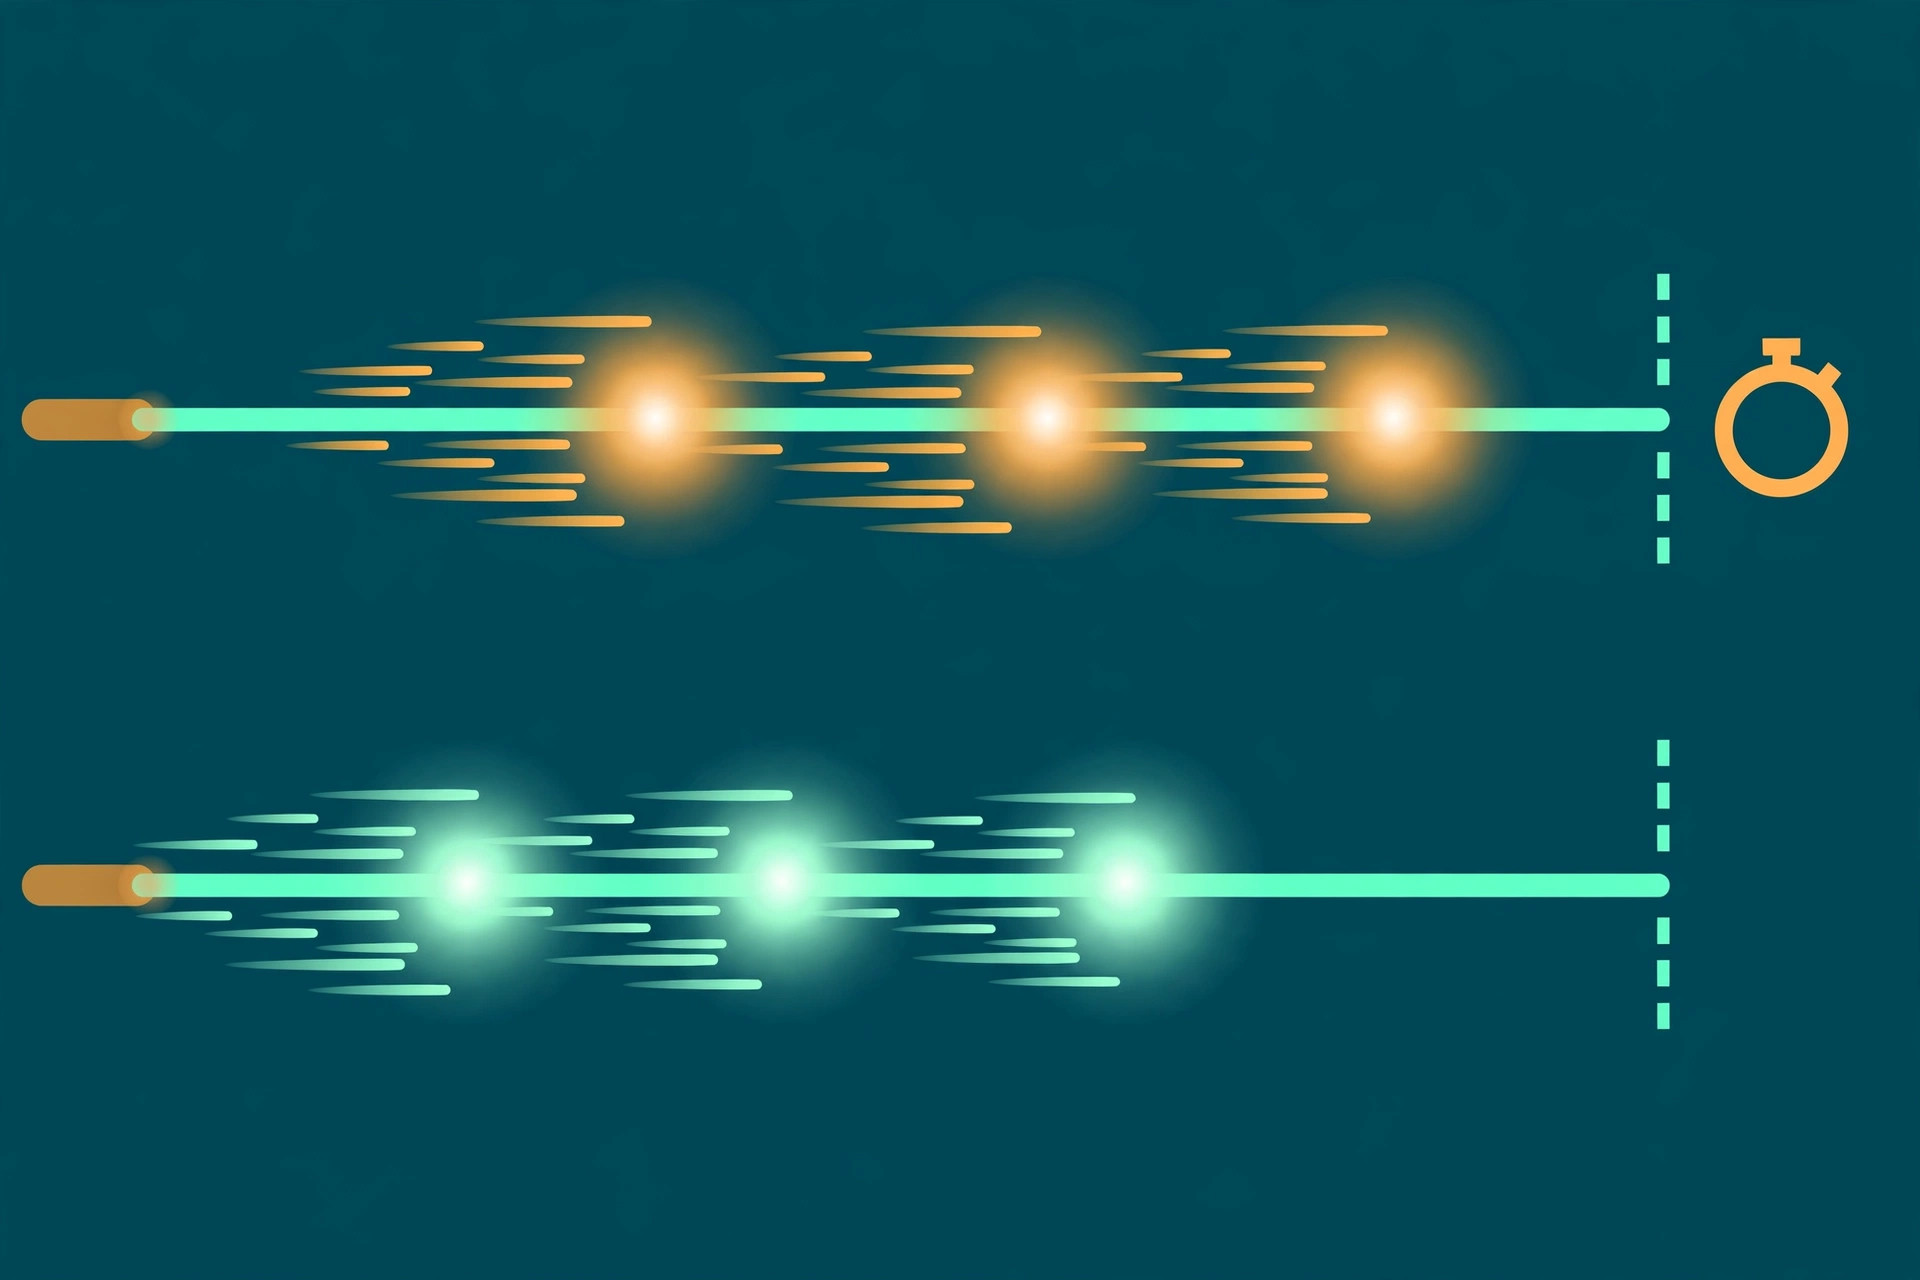
Newcomers assume a faster link fixes latency. Watch what actually happens when two identical packets race — one traveling far on a blazing link, one traveling a short distance on a slow link. It is like racing a sports car across the country against a bicycle across town: the bicycle wins, because distance dominates.
Why averages lie
A link can have 2 ms average latency and ruin a trade on the one spike that matters. HFT and voice care about the tail: p99, p99.9. (p99 = the 99th percentile: 99% of packets were faster than this number, 1% were slower.) The tail comes from micro-bursts — tiny bursts that momentarily fill a buffer and add milliseconds of jitter (variation in delay). Tools that sample once a second never see them — like a security camera taking one photo per minute and missing the burglary.
TCP makes latency multiply
Every round trip taxes TCP twice: once to fill the pipe and once to recover from loss. The rule of thumb is the bandwidth-delay product: BDP = bandwidth × RTT. At 1 Gbps with 100 ms RTT, you need roughly 12.5 MB of TCP window in flight — without window scaling, you get 1/200th of the line rate. Run the numbers on our bandwidth-delay calculator; most "slow links" over long distances are window problems, not capacity problems.
Measure like the network owes you money
- ping/traceroute are the blunt instruments. ping sends ICMP echo requests and times the reply; but ICMP responses from routers can be rate-limited, and the path can differ per-protocol. Use them to find hops, not to price latency.
- mtr over minutes beats traceroute once. mtr combines ping and traceroute continuously, surfacing per-hop packet loss and jitter.
- Applications are the truth. Capture with Wireshark and read the timestamps between request and response. That number is what your users pay.
- One-way delay demands synced clocks. Without PTP (or at least solid NTP) on both ends, "one-way 4 ms" is a guess. When the sync itself has a hard number to hit — MiFID II's 100 µs traceability to UTC — budget the chain with the PTP timing budget calculator, then simulate it over time in the PTP/SyncE network-wide timing simulator.
- Hardware timestamps. NICs that timestamp at the wire remove the host's jitter from the measurement.
- Model the whole chain before you buy. Add every stage in the tick-to-trade calculator. It shows which component owns your microseconds.
On the wire: what a PTP Sync message looks like
This part is genuinely intricate — here's the shape of it. One-way delay claims stand on synchronized clocks: every machine must agree on what time it is, to the microsecond. PTP achieves that by having a master clock broadcast "the time was T when I sent this" messages, and this is what one looks like on the wire. The fields that matter for latency work are highlighted:
0000  01 1b 19 00 00 00 00 11 22 33 44 55 88 f7 00 02
0010  00 2c 00 00 02 00 00 00 00 00 00 00 00 00 00 00
0020  00 11 22 ff fe 33 44 55 00 01 12 34 00 fd 00 00 6a bc
0030  0a 80 1d cd 65 00
  destination MAC (PTP multicast)	  correctionField	  originTimestamp
Destination MAC 01:1b:19:00:00:00 — PTP multicast
A special multicast address every PTP-aware device listens to — like a PA system frequency. One Sync message reaches every clock in the broadcast domain at once.
messageType 0 — Sync: "the time was T when I sent this"
The master clock's announcement. The slave compares T against its own local arrival time; the difference is its clock offset — how far fast or slow it is.
flags 0x0200 — two-step: the timestamp arrives later
The exact transmit time comes in a Follow_Up message a moment later — "the time was T" first, the precise T right after. Two-step is the norm on real NICs.
correctionField — 0 here; every switch adds its residence time
Each transparent clock adds the time the message spent inside it to this field — like each relay runner noting how long they held the baton. The PTP timing budget calculator sums exactly these per-hop additions.
originTimestamp — the time itself
48 bits of seconds plus 32 bits of nanoseconds. This is the number the slave disciplines its clock to — the actual "it is now exactly this time" value.
logMessageInterval −3 — a Sync every 125 ms
The interval is 2−3 seconds. Frequent Syncs let the slave's servo track clock wander continuously — small, constant corrections instead of rare big ones.
The practical knobs
Before throwing hardware at latency: keep queues shallow (a giant buffer trades loss for delay — bufferbloat), keep MTUs consistent end-to-end to avoid fragmentation, prefer cut-through switches on the hot path, and remove middleboxes you do not need. For trading-grade work, the playbook goes deeper — kernel bypass (DPDK) or FPGA-based feeds — but 90% of real networks never need it.
- Multicast, Explained: Why Exchanges Send One Feed and the Network Copies It — how one market-data feed reaches every subscriber without the sender making a copy per receiver.
- Latency has four components: propagation, serialization, processing, and queuing.
- Fiber gives you ~5 ms of one-way delay per 1,000 km — physics sets the floor.
- Averages lie: jitter and worst-case queues decide real performance.
- Measure application latency with real timestamps, not just ping.