Hyperscaler Network Engineer: Networking at Cloud Scale
Inside the network orgs of the big clouds: how hyperscaler networking genuinely differs from enterprise, the automation-first skill stack, what the interviews test — and honest routes in.
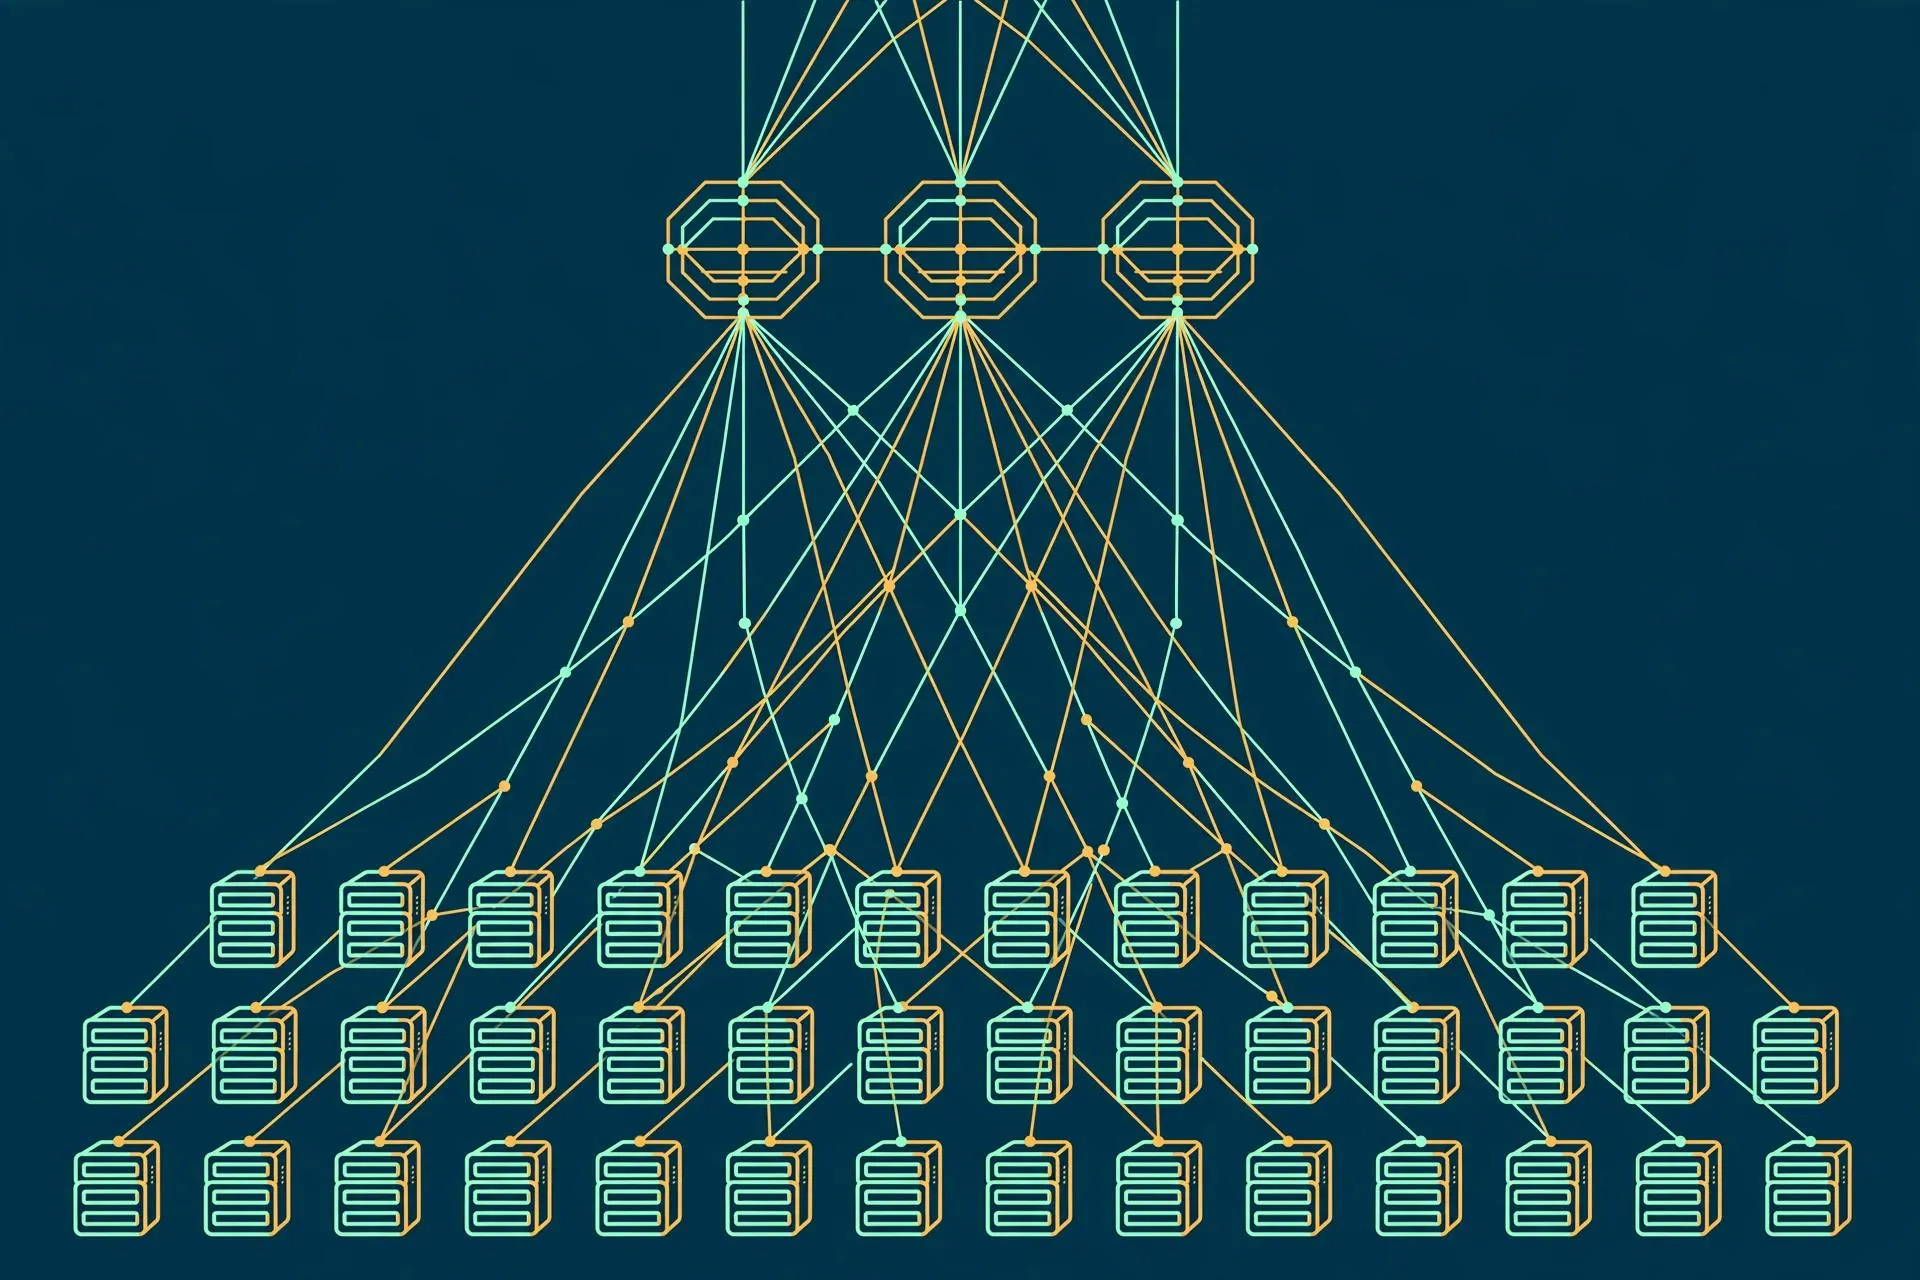
Think of it as a power grid, not a kitchen
An enterprise network engineer is a chef cooking dishes one at a time. A hyperscaler network engineer runs the city's power grid: nobody walks to one transformer and flips it by hand — you change the system, and the system changes ten thousand transformers at once. If you catch yourself doing something by hand twice, that's a bug in your process. That instinct — automate everything, touch nothing individually — is the single signal these interviews look for.
What "hyperscaler" means here
Hyperscalers are the tiny club of companies running global compute infrastructure: AWS, Google Cloud, Azure, Meta, Oracle Cloud, Alibaba Cloud, and a handful of others. "Cloud scale" means numbers that break enterprise assumptions: fabrics with thousands of switches, regions that add capacity continuously, and change volume no human team could type by hand.
The network engineers there are still network engineers — they reconcile BGP states and chase packet loss — but the operating model is the thing to understand. It is software engineering applied to networks.
The fabric: what "cloud scale" looks like
The building block of every cloud data center is the Clos fabric — a grid of leaf switches (each connecting a rack of servers) and spine switches (connecting the leaves). Every leaf connects to every spine, so traffic spreads evenly across many equal paths — a technique called ECMP (equal-cost multipath: the network splits traffic across all shortest paths instead of picking one). One pod is a few dozen switches; a region is thousands of pods. The newest twist on this design is the AI cluster, which runs two fabrics side by side — a front-end for management and inference, and a back-end hauling GPU collective traffic: Why AI Clusters Run Two Networks: Front-End vs Back-End Fabrics Explained. Watch the packet storm:
How the network genuinely differs
How the network genuinely differs
| Enterprise | Hyperscaler | |
|---|---|---|
| Fabric | Campus + WAN + data center; hierarchy everywhere | Massive Clos (spine-leaf) fabrics; east-west traffic dominates |
| Control plane | OSPF/IS-IS inside, eBGP at the edge | BGP everywhere — eBGP-as-underlay designs (RFC 7938) are common |
| Hardware | Vendor platforms, vendor NOS | Vendor hardware or open designs; often in-house or open NOS (e.g., SONiC, the Microsoft-contributed open-source NOS) |
| Changes | Change windows, emailed tickets, careful hands | Config as code: pipelines, code review, canary rollouts, automated rollback |
| Observability | SNMP, syslog, dashboard-of-dashboards | Streaming telemetry, flow data at scale, bespoke tooling |
| Unit of work | A device | A fleet of thousands — nothing is done one router at a time |
Decoding the jargon in that table: eBGP-as-underlay means running BGP between every switch inside the data center (RFC 7938 made it respectable); canary rollouts mean testing each change on 1% of the fleet before the rest; east-west traffic is server-to-server chatter inside the data center.
The teams you'll find
Network orgs at hyperscalers are dozens to hundreds of engineers split by function: fabric/DC network engineering (the Clos), backbone/WAN (between regions), edge/metro (peering, CDNs, PoPs), network capacity (forecasting and builds), network automation (the tooling everyone else uses), and SRE-style operational roles with pagers. Early careers usually start in operations or on a specific fabric team; design and automation roles open once you've felt the scale.
The skill stack
- Unshakeable fundamentals. IP addressing, BGP, TCP, ECMP, packet walks. The cloud's protocols are the same protocols — the depth bar is just higher. If BGP and TCP internals don't feel like home turf, start there. And make ECMP concrete: watch identical hash seeds collapse a Clos fabric's traffic onto a few diagonal paths in the ECMP hash polarization visualizer — hash polarization is the failure mode every fabric interview eventually reaches. For the broader BGP picture — looking glasses, RPKI, hijack checks — the BGP toolkit is worth an afternoon.
- Linux, seriously. Not "I have run ls" — namespaces, veth pairs, nftables, systemd, package and config management. Linux is the platform; routers are applications.
- Real programming. Python first, Go increasingly. Reading code reviews, writing automation, parsing structured data — "I can script a little" is exactly the gap to close.
- Systems thinking. Git, CI/CD, testing, rollbacks, blameless postmortems. Your config change is someone else's fleet outage unless the pipeline exists.
- Telemetry fluency. Streaming telemetry, structured events, and the math to ask "is this spike real?" before waking anyone.
What interviews test
Expect a mix of: coding screens (leetcode-light for most roles, heavier for automation-heavy ones), protocol deep dives ("how does BGP converge after a link flap in a Clos?"), design questions ("design monitoring for a million-server fabric" — they're scoring your reasoning about scale), and behavioral rounds. The consistent theme: show you think in systems and failure modes, not recipes.
Honest routes in
| Route | How it works |
|---|---|
| Enterprise DC / backbone roles | The most common path: do real BGP, real automation, real incidents on serious hardware, then interview at scale. |
| NOC / ops at a cloud or CDN | Operations teaches you the failure modes everything else is built on. Operators who automate their way out of tickets get noticed. |
| SRE adjacent | SRE teams at any product are where software engineers learn production networking — and where network engineers learn software habits. |
| Open source | Genuine contributions to SONiC, FRRouting, Ansible network modules, or an open telemetry project are a real signal — and public. If SONiC is new to you, our SONiC explainer covers why AI data centers run the open-source NOS. |
| New grad | The hyperscalers hire juniors, but the network-entry bar is steep: fundamentals, programming, and ideally internships with real (not paper) networking in the job history. |
The trade-offs nobody tells you
Cloud networking pays well and the scale teaches you things nothing else can. It is also, by design, automated — your job is partly building the machine that replaces manual network engineering. Some people find that thrilling; some miss touching hardware. On-call at hyperscaler scale is serious engineering, not ticket-clicking, but it's still on-call at 3 a.m. And note: the work is often narrower than enterprise — you might know one system very deeply for years. Go in clear-eyed about which shape you prefer.
Your next steps
Work through the free guides in the order of the skill stack above; open the data-center capacity planner and rebuild your mental model of a fabric before you design one; run the bandwidth-delay math on a 400 Gbps fabric link to feel the numbers. And start the Linux + Python pair today — it's the gap that keeps more people out of these roles than any networking topic.
- Hyperscaler networking means scale and software: Clos fabrics, automation-first ops, config as code.
- The skill stack is networking fundamentals + Linux + real programming + systems thinking.
- Expect coding screens, deep protocol dives, and design discussions in interviews.
- Real routes in exist from enterprise DC roles, NOC work, SRE, and open-source contributions.