Why AI Clusters Run Two Networks: Front-End vs Back-End Fabrics Explained
AI clusters don't run one network — they run two. The front-end fabric handles management, storage, and inference traffic; the back-end fabric exists for one job: GPU-to-GPU collective communication at microsecond latency. Here's why operators split them.
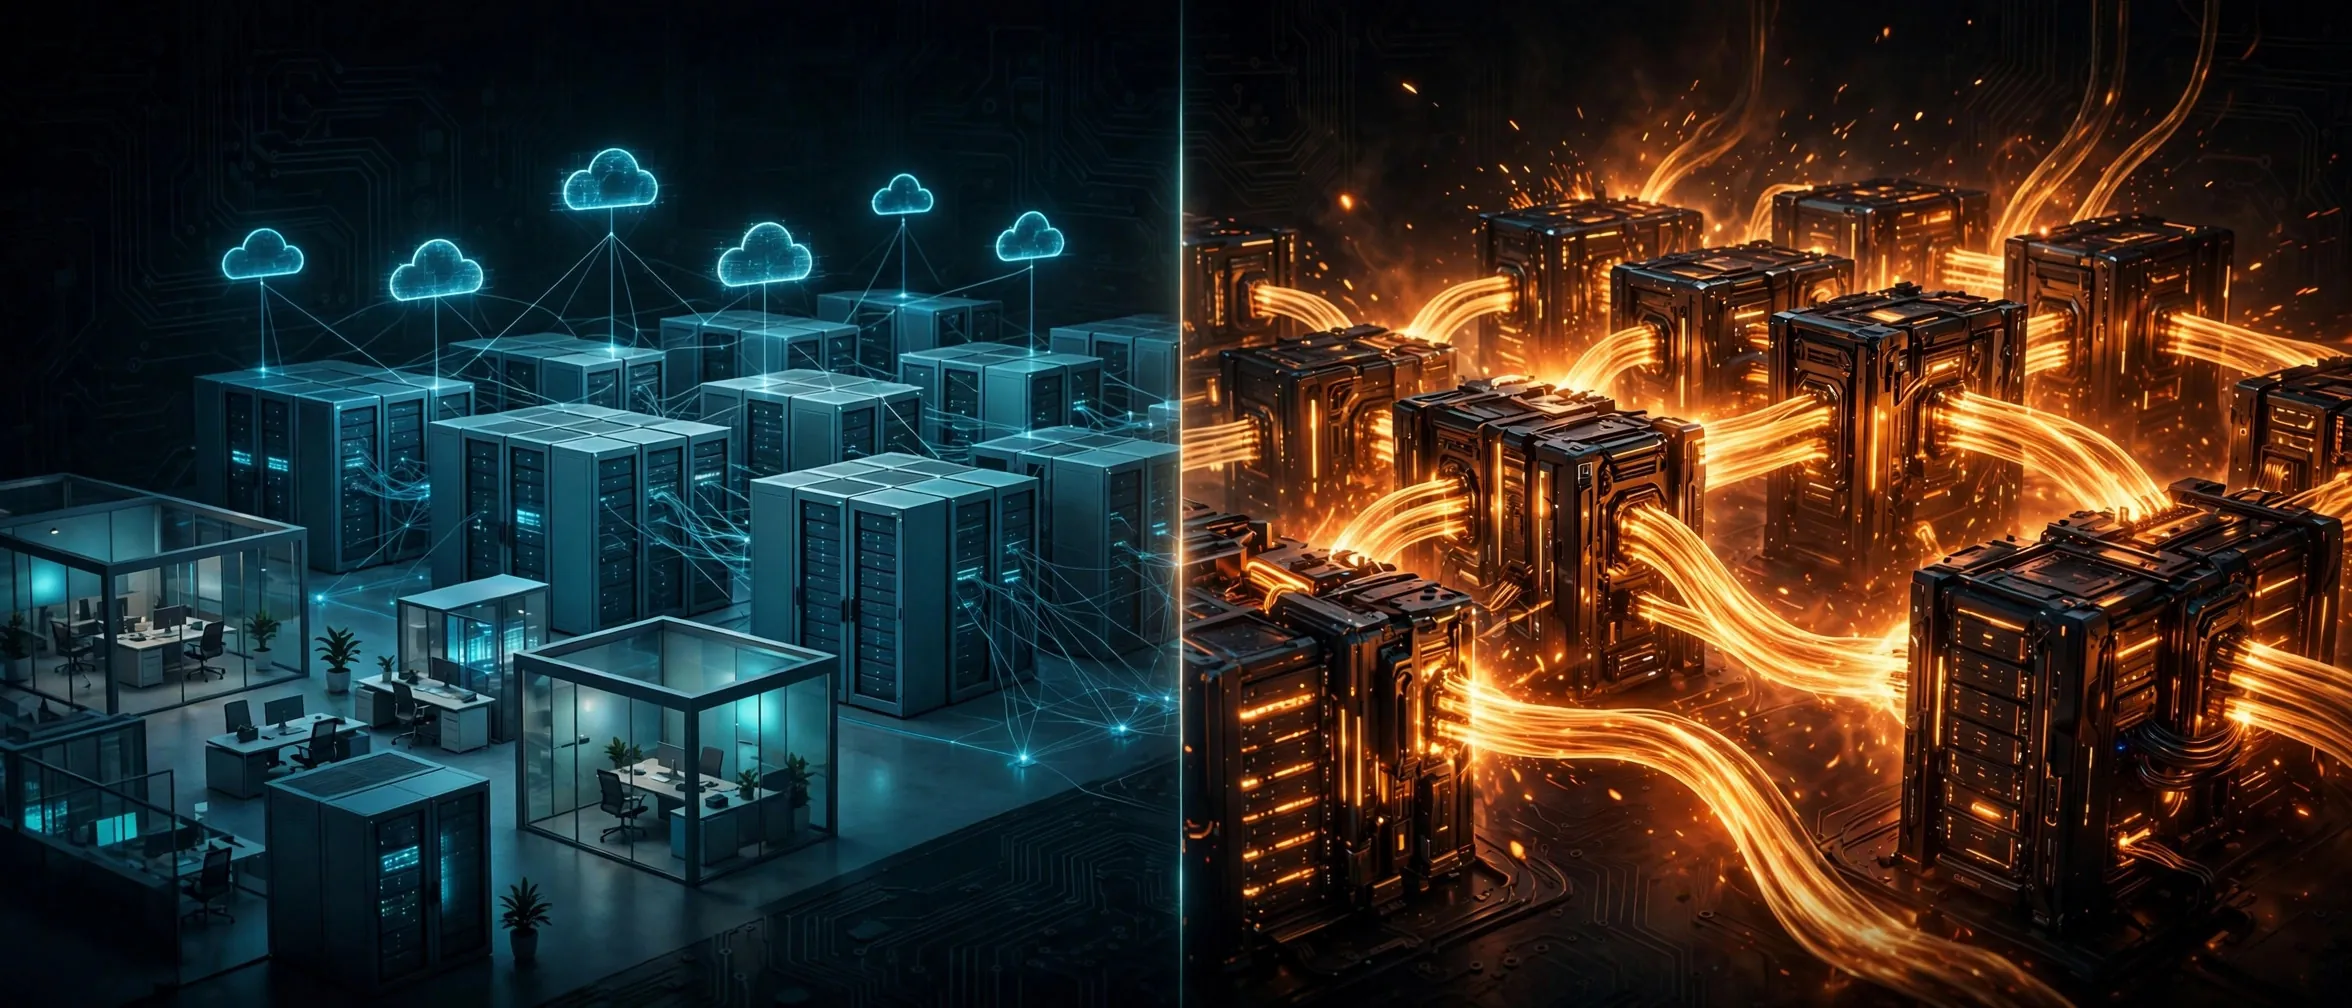
The city with two transportation systems
Imagine a city that needs to move two very different things: commuters, mail, and food deliveries — and, separately, a million tons of steel between factories. You would never run the freight trains down Main Street at rush hour. You would build a dedicated rail line for the steel and leave the streets for everything else.
An AI cluster does exactly the same thing with packets. It runs two networks: a front-end fabric that acts as the city streets, and a back-end fabric that acts as the freight rail. (The industry word "fabric" just means the whole network inside a data center — all the switches and cables working as one.) If you have ever wondered why AI data center diagrams always show two sets of switches, this is why.
This month, the split became official
The two-fabric design stopped being insider knowledge recently. Cisco's Secure AI Factory with NVIDIA — expanded to a rack-scale architecture in August 2026 (designing at the scale of whole racks working as units, not individual servers) — is built around it: Cisco's own Silicon One switches on the front-end fabric, NVIDIA Spectrum-X-based switches (the Cisco N9100: 64 ports of 800G, 51.2 terabits per second of switching) on the back-end, all managed as one system under Cisco Nexus One. The Supermicro rack-scale systems in that architecture became orderable this month, October 2026, targeting enterprises, neocloud providers (newer cloud companies built specifically for AI workloads), and sovereign cloud operators (national clouds run for governments).
And the compute side explains why the network side has to be special: a Vera Rubin NVL72 rack draws 190–230 kW and requires 100% liquid cooling — Supermicro ships four 110 kW power shelves per rack. When one rack pulls as much power as a city block, its network is not an afterthought. (If you want to see this gear in person, the OCP Global Summit runs October 12–15 in San Jose.)
What the front-end fabric carries
The front end is the city streets. It carries:
- Management and control — SSH sessions (secure remote logins to each machine, like a private phone line for administrators), APIs (the control knobs software uses to talk to hardware), configuration pushes, and telemetry streams (continuous health reports — temperature, errors, traffic levels) from every switch and server.
- Storage — training datasets flowing in, model checkpoints flowing out (a checkpoint is a saved snapshot of the half-trained model, so a crash does not lose days of work).
- North-south traffic — inference requests arriving from users, answers going back. ("North-south" means traffic entering or leaving the data center; "east-west" is traffic staying inside it.)
It is ordinary Ethernet/IP — the kind of network offices have run for decades. It can run a vendor NOS or an open one like SONiC (see our SONiC explainer). Reliability matters here, but a dropped packet is just a retransmit. Nothing catches fire.
What the back-end fabric carries
The back end is the freight rail, and it hauls exactly one cargo: collective communication. Here is the picture: teaching an AI model means showing it billions of examples, and after each batch every GPU has computed its own correction notes — called gradients ("here is how wrong we were, and which way to adjust"). Before anyone moves on to the next batch, all thousands of GPUs must swap those notes with each other, in lockstep. That synchronized swap has names — all-reduce (everyone combines everyone's notes into one agreed result) and all-gather (everyone collects everyone else's notes) — and it moves gigabytes, over and over, thousands of times per training run. Think of a rowing crew: eight rowers are only fast if every oar hits the water at the same instant. One rower out of sync and the whole boat wobbles.
Three things make this fabric different from any office network you have managed:
- RDMA over Converged Ethernet (RoCE). The network card reads and writes GPU memory directly, bypassing the CPU and the operating system entirely. ("RDMA" = remote direct memory access: one machine's network card writing straight into another machine's memory, no middlemen, no waiting in line at the CPU.)
- It is lossless. Priority Flow Control (PFC) tells senders to pause instead of dropping packets when buffers fill — like a traffic cop holding cars at an on-ramp rather than letting the intersection jam. ECN (explicit congestion notification) marks packets early so senders slow down before queues explode — an early-warning flasher instead of a crash. A dropped packet here means an expensive retransmit right in the middle of a synchronized exchange, stalling every GPU at once.
- Microsecond latency is the target. In synchronous training, every GPU waits for the slowest one. One delayed packet does not just slow a single flow — it stalls the entire training step. Engineers call this the straggler effect: the crew boat moves at the speed of its slowest rower.
Why not one big network?
Five reasons operators keep the fabrics apart — each one is really about the same idea: blast radius (how far the damage spreads when something breaks). You do not store fireworks in the pantry.
- The traffic patterns are opposites. Front-end traffic is millions of small, bursty, latency-tolerant flows — like city traffic. Back-end traffic is a small number of enormous, synchronized, latency-intolerant flows — like the freight train. No single tuning serves both.
- Blast-radius isolation. A broadcast storm or a misconfigured firewall rule on the management network must never be able to stall a training run worth thousands of GPU-hours. Separate networks mean one side's bad day cannot touch the other.
- Independent scaling. Adding inference capacity? Grow the front end. Adding GPUs? Grow the back end. Neither forces the other to change — like adding lanes to the highway without rebuilding the rail line.
- Congestion control conflicts. The back end needs lossless behavior via PFC; running PFC across a mixed network invites head-of-line blocking (one slow packet blocking everyone behind it, like a stalled car at a toll booth holding up the whole lane) and PFC storms (pause signals cascading from switch to switch, freezing traffic that had nothing to do with the original congestion). Keep the lossless domain tight and the front end lossy.
- Separate failure domains. You can reboot the front-end fabric's control plane without touching a running training job.
The power forcing function
The two-network design is not only about packets. NVL72-class racks at 190–230 kW each mean the data center itself is being redesigned around liquid cooling and new power distribution — a new 800V DC power architecture is replacing the old 48V distribution in these facilities. (Think of it as upgrading a building's plumbing from garden hoses to fire mains: pushing the same power at higher voltage means thinner cables and less energy wasted as heat.) The network rides the same rack-scale logic: short, dense, purpose-built fabrics instead of one general-purpose cloud network. The building, the power, the cooling, and the network are all being co-designed now.
What this means for your skills
If you work in data center networking, the back-end fabric is where the demand is moving:
- Lossless Ethernet tuning — PFC, ECN, and DCQCN (data center quantized congestion notification — the specific algorithm that tells senders exactly how much to slow down) are the back-end's holy trinity.
- RDMA/RoCE fundamentals — what changes about troubleshooting when the CPU never sees the packet. (Normally you can capture traffic on the server; with RDMA the data flies straight from network card to GPU memory, so your usual tools go blind — you have to watch the network itself.)
- Telemetry-first operations — at this scale you do not CLI into switches (typing commands one by one into a switch's text console); you watch continuous streams of measurements. A microburst — a traffic spike lasting millionths of a second — can stall training, and only fine-grained telemetry sees it.
- Traffic placement judgment — knowing which traffic belongs on which fabric. Test yourself below.
- ECMP behavior on AI fabrics — hash polarization on the back end is catastrophic: one bad hash and a whole spine link sits idle while GPUs wait. (ECMP spreads traffic across parallel links by hashing each flow; "polarization" means the hashes accidentally agree and pile onto the same link.) See our ECMP explainer and try the ECMP hash polarization visualizer.
For the career view, see the hyperscaler network engineer career path.
Three mistakes to avoid
- Running collectives over the front-end fabric "temporarily." The temporary becomes permanent, and one noisy neighbor — some unrelated traffic hogging the shared road — stretches every training step.
- Treating the back end like a LAN — same SNMP polling (the old standard protocol for asking devices "how are you doing?" every few minutes), same thresholds. It needs microburst-level telemetry, or you are blind to the exact events that stall training.
- One congestion policy everywhere. PFC enabled on mixed traffic invites head-of-line blocking; keep the lossless domain tight and the front end lossy.
Which fabric does it belong on?
- AI clusters split networking into a front-end fabric (management, storage, north-south inference traffic) and a back-end fabric (GPU-to-GPU collectives).
- The back-end fabric is lossless and latency-obsessed: RoCE/RDMA, PFC, and ECN keep all-reduce collectives moving at microsecond scale.
- Operators split them because the traffic patterns are opposites, for blast-radius isolation, and for independent scaling — Cisco's rack-scale AI Factory puts Silicon One on the front end and Spectrum-X on the back end.
- The skills that pay: lossless Ethernet tuning, RDMA/RoCE, telemetry-first operations, and knowing which traffic belongs on which fabric.